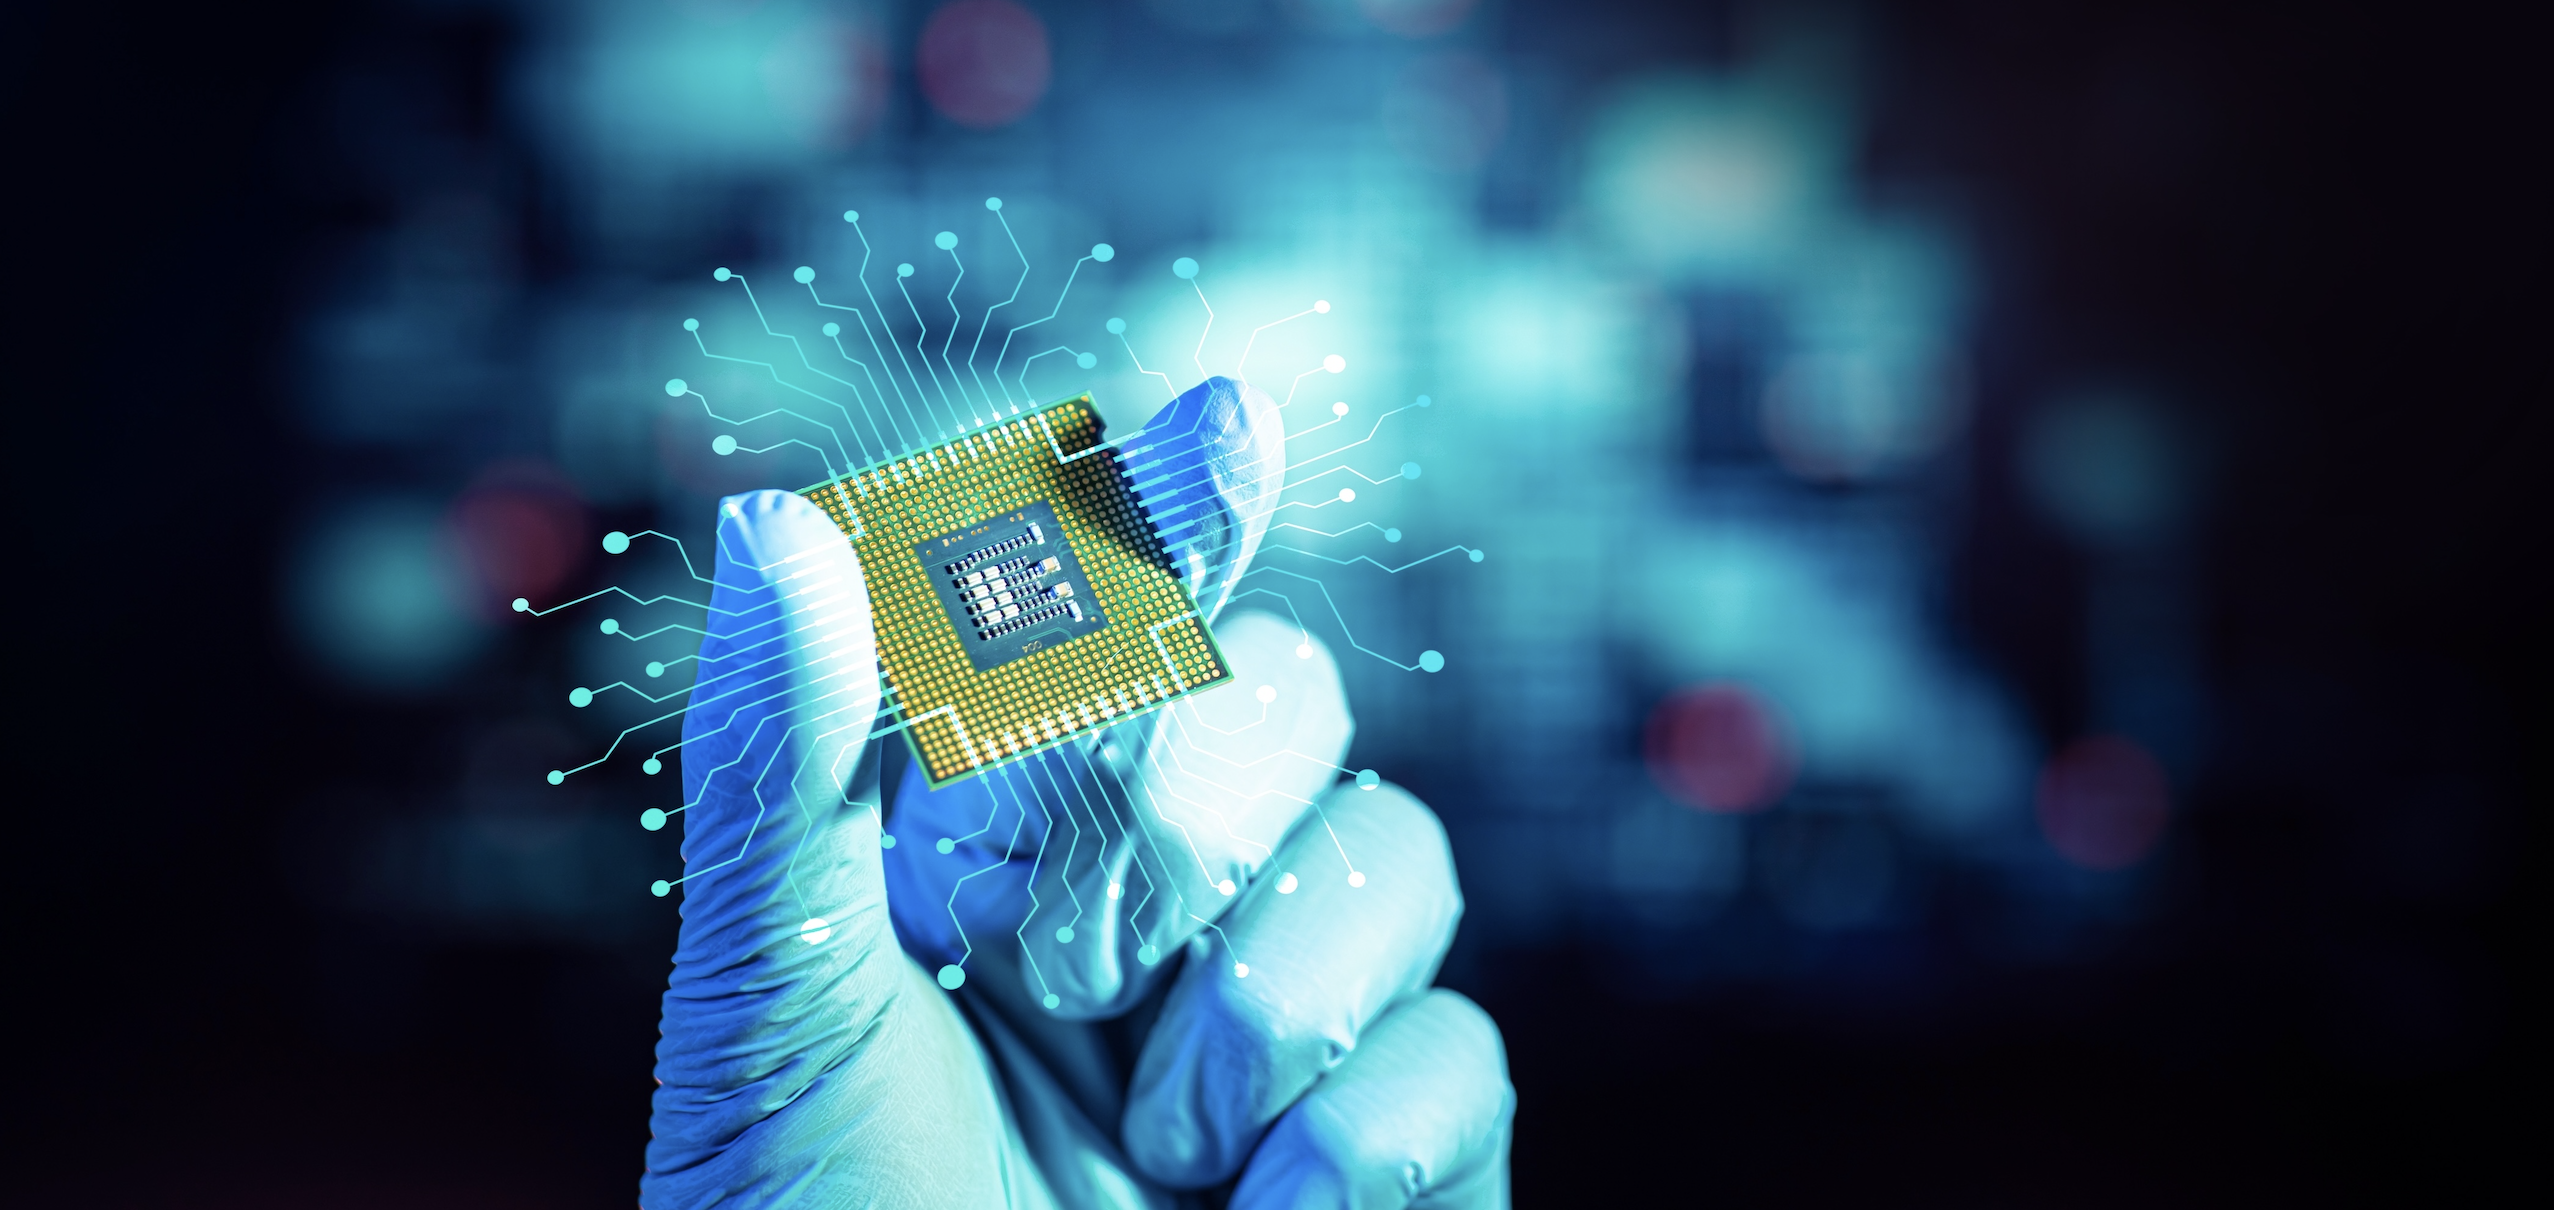
The network-on-chip technology has the potential to improve the efficiency of AI accelerators. The efficiency of accelerators relies on their ability to process information faster, utilize memory bandwidths efficiently and ensure a high rate of data transfer.
Communication between processing modules
Artificial intelligence accelerators can be utilized in a variety of applications, ranging from simplified neural networks to complex computations. They involve hundreds or thousands of parallel processing units that communicate with each other to perform complex processes. The network on the chip offers a method to address the communication needs of such a large set of processing units by establishing a communication infrastructure that allows processors to pass and receive information.
The traditional bus architecture can become overwhelmed in such cases as the available bandwidth has to be shared between all of the processing units. The NoC Interconnect approach utilizes switches that can allow multiple data transfer sessions to be held at once, which can reduce bottlenecks and allow the accelerator to utilize its processing power more efficiently. The network infrastructure provides a channel through which different processing units can send and receive data, which allows the AI accelerator to operate without unnecessary delays.
Parallel Computing and Resource Utilization
Most AI-related tasks involve extensive use of parallel processing. Deep learning neural networks such as convolutional ones or the transformer architecture can involve thousands of operations that take part simultaneously. This requires an equal number of processing cores to be utilized, which requires the cores to communicate with each other to establish the rate of data transfer and share intermediate data.
The described inefficiencies can be eliminated by utilizing the on-chip network infrastructure, which would reduce such delays. Such unnecessary delays can also be caused by the processors’ inability to continuously provide input data to a set of cores. Matrix multiplication cores, for instance, require a continuous supply of data to be able to perform the calculations at the required speed. This, combined with the utilization of multiple processing cores, requires a high bandwidth to be allocated to each core. An efficient NoC design will reduce such bottlenecks and optimize the usage of accelerator resources.
Latency and Communication Efficiency
The latency of AI accelerators is a crucial factor in their performance, and it is determined by the time that it takes for data to be transferred between processing cores. Any additional time spent on communication between processing cores adds up to the total computation time of the AI accelerator. The network core can reduce such delays by eliminating unnecessary communication steps and ensuring that data is delivered directly between the processing cores. It can achieve the described goals by taking the physical location of processing cores in the network into account and reducing the number of switches that have to forward the given data.
The NoC switch architecture can also optimize the delivery of data by utilizing different types of routing algorithms and ensuring that the most demanding connections are prioritized. The described properties can reduce the latency overheads of the accelerator network, which results in better utilization of the accelerator’s resources. The design of the router switch and bandwidth allocation strategies also affect the described characteristics as the NoC infrastructure can only utilize the available resources to forward data. The mentioned limitations become a major issue in AI accelerators due to the high amount of data that they have to process.
Power Consumption and Thermal Management
The power consumption of the NoC infrastructure is a crucial factor in the performance of the AI accelerator. It is a major limiting factor in accelerators as their processing elements require a substantial amount of energy to operate. The NoC design can affect the power consumption directly by affecting the length of the wire that is used to transmit data and the amount of unnecessary data that the accelerator has to process.
The elimination of intermediate switches, as well as the optimization of data transmission, can reduce the amount of power that is wasted on superfluous data transfers. The lower overheads of the NoC infrastructure allow more energy to be utilized for computations, which result in better performance. The described advantages can be achieved through the optimization of the switch locations and the elimination of unnecessary communication channels. The characteristics of the switch itself and associated infrastructure also affect the power consumption and bandwidth utilization of the accelerator.
Scalability and Accelerator Design
The increasing complexity of AI models requires accelerators that utilize more processing elements and a greater amount of memory. The network on chip allows such accelerators to scale their performance by eliminating the need for shared memory. The various elements of the NoC switch design can be used depending on the requirements of the accelerator. Mesh and ring topologies, for example, have different bandwidth utilization and wiring requirements, so a choice has to be made based on the needs of the accelerator. The memory bandwidth, in particular, is a crucial factor in the performance of an AI accelerator.
The design of the network infrastructure can greatly impact the efficiency of the accelerator in terms of bandwidth, which determines how much data it can access per second. A greater amount of processing elements puts additional strain on the accelerator, and it has to rely on memory caching to continue operating. The proper utilization of such infrastructure is crucial for the acceleration of AI model processing. The described challenges can be addressed by designing a NoC infrastructure that reduces unnecessary memory accesses and takes the on-chip memory’s characteristics into account. The mentioned challenges can be addressed through simulation and performance testing to ensure that the accelerator would be able to support the necessary data transfer rates and avoid bottlenecks.
Conclusion
Network-on-chip technology allows AI accelerators to operate more efficiently by improving the data transfer rates between processing cores, optimizing processing elements utilization and reducing communication overheads. The described advantages have a considerable impact on the performance of the accelerator, but they are reliant on the capabilities of the underlying infrastructure. The efficiency of the NoC design is paramount to the performance of the accelerator, and it can be optimized through bandwidth and latency management techniques.
 AI tools to find & convert leads.